Document retrieval / Assistant demo
CouncilMate AI
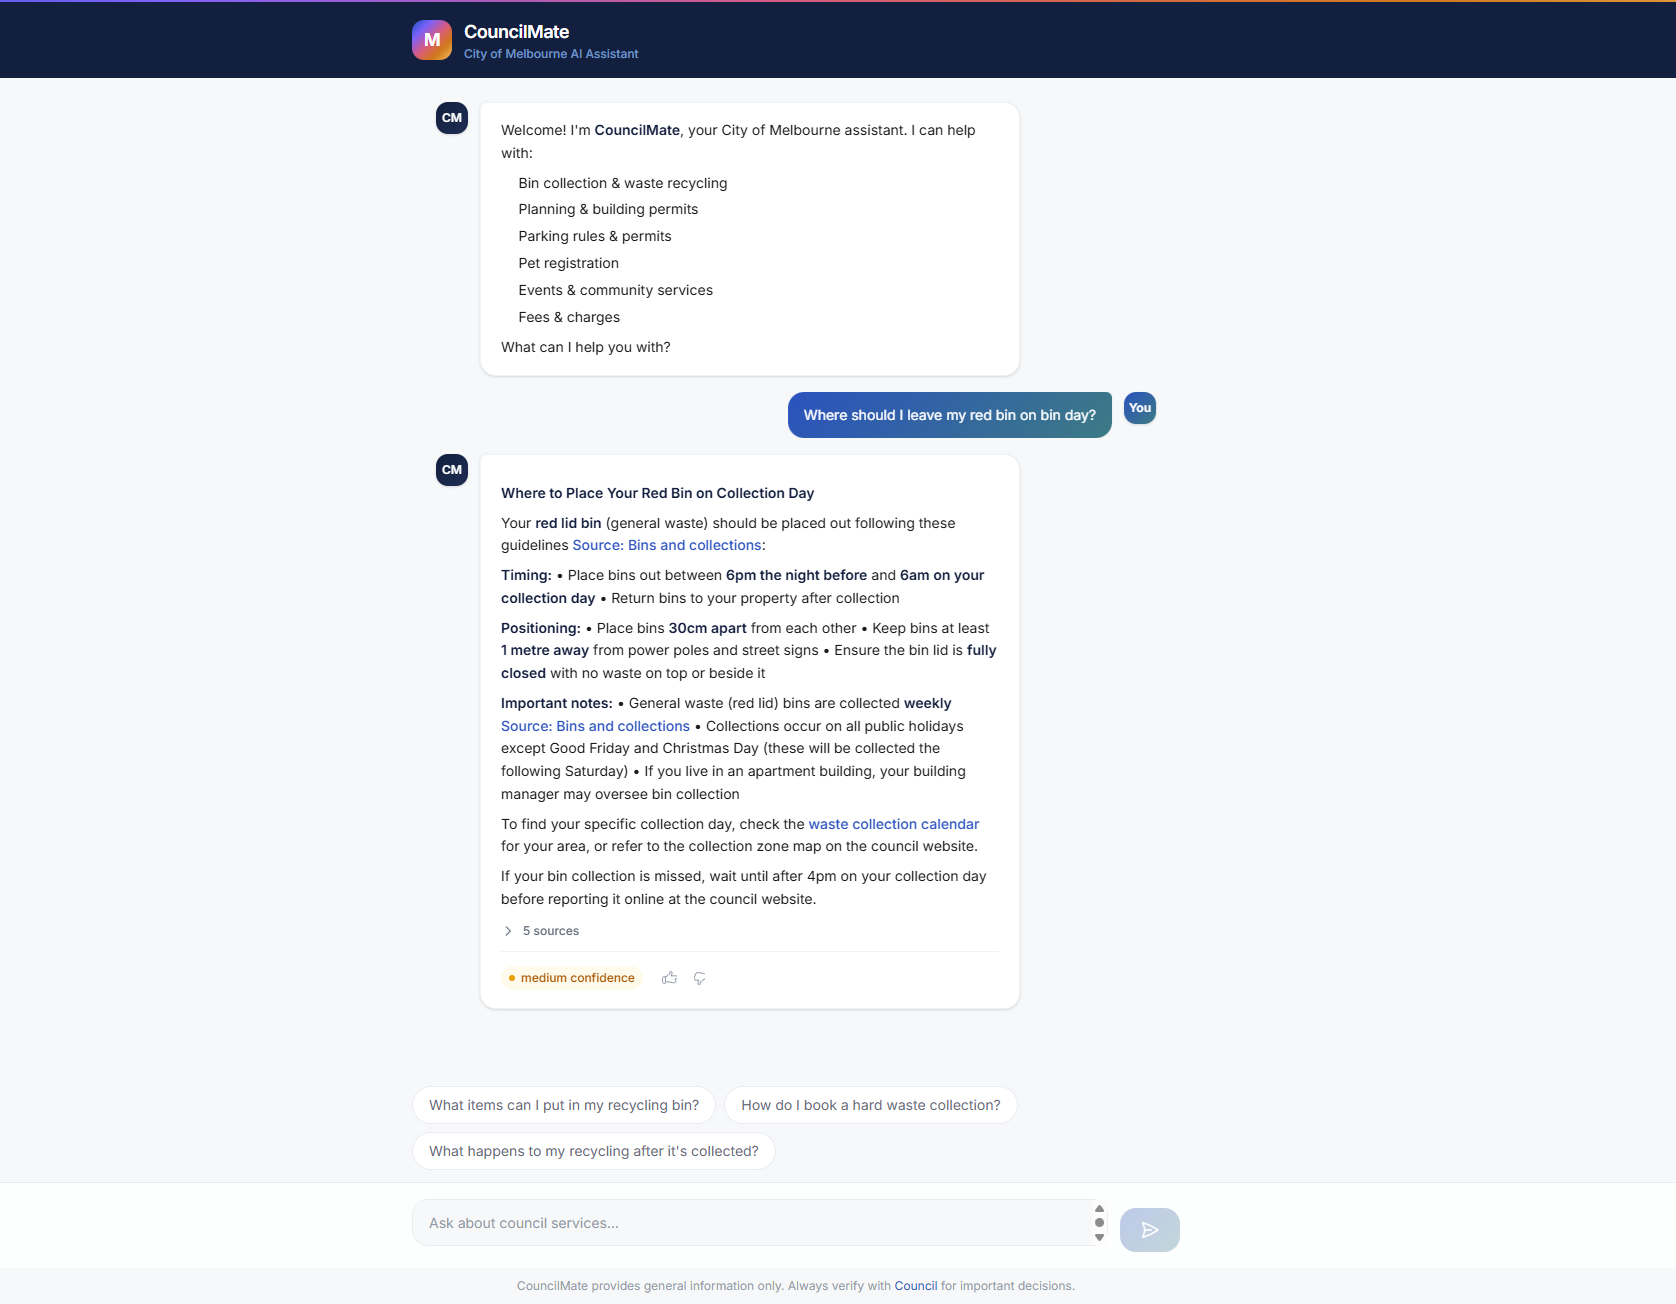
Find council-service information through a question-and-answer interface with source references.
- My contribution
- I built the council-information retrieval assistant described in this portfolio, including its ingestion, retrieval and answer-generation flow.
- Tools & methods
- Python · FastAPI · ChromaDB · Scrapy
The problem
What this project investigates
Council-service information is spread across pages and documents. The project brings relevant passages into a single answer while retaining a path back to the source.
The build
What I built
The documented pipeline crawls council pages and PDFs, chunks and embeds the content, retrieves passages from ChromaDB and supplies them to a language model through a FastAPI backend.
Technical choices
Decisions behind the build
Keep source metadata
Metadata travels with retrieved chunks so an answer can point back to the underlying information.
Separate ingestion from answering
Scrapy and Playwright handle collection; the API handles retrieval and generation.
Current status
What the evidence shows
The portfolio includes a screenshot and a demo address. It does not include a retrieval benchmark, freshness audit or evidence of council adoption. Source references help review an answer; they do not guarantee correctness.
Further work & evidence gaps
Document crawl dates, failed retrievals and citation accuracy before making stronger reliability claims.